Would your AI service manager save the customer—or close the deal?
Imagine a busy repair shop in its worst week: customers are churning, a competitor is circling, and a tempting shortcut could compromise trust. An AI assistant might spot the trouble and recommend the right move. But would it follow through when the decision gets hard? Firmulate is testing that gap in a live, watchable experiment: not just how models talk about running a company, but how they make decisions under pressure. Watch the live company.
A company-sized test, not a chat demo
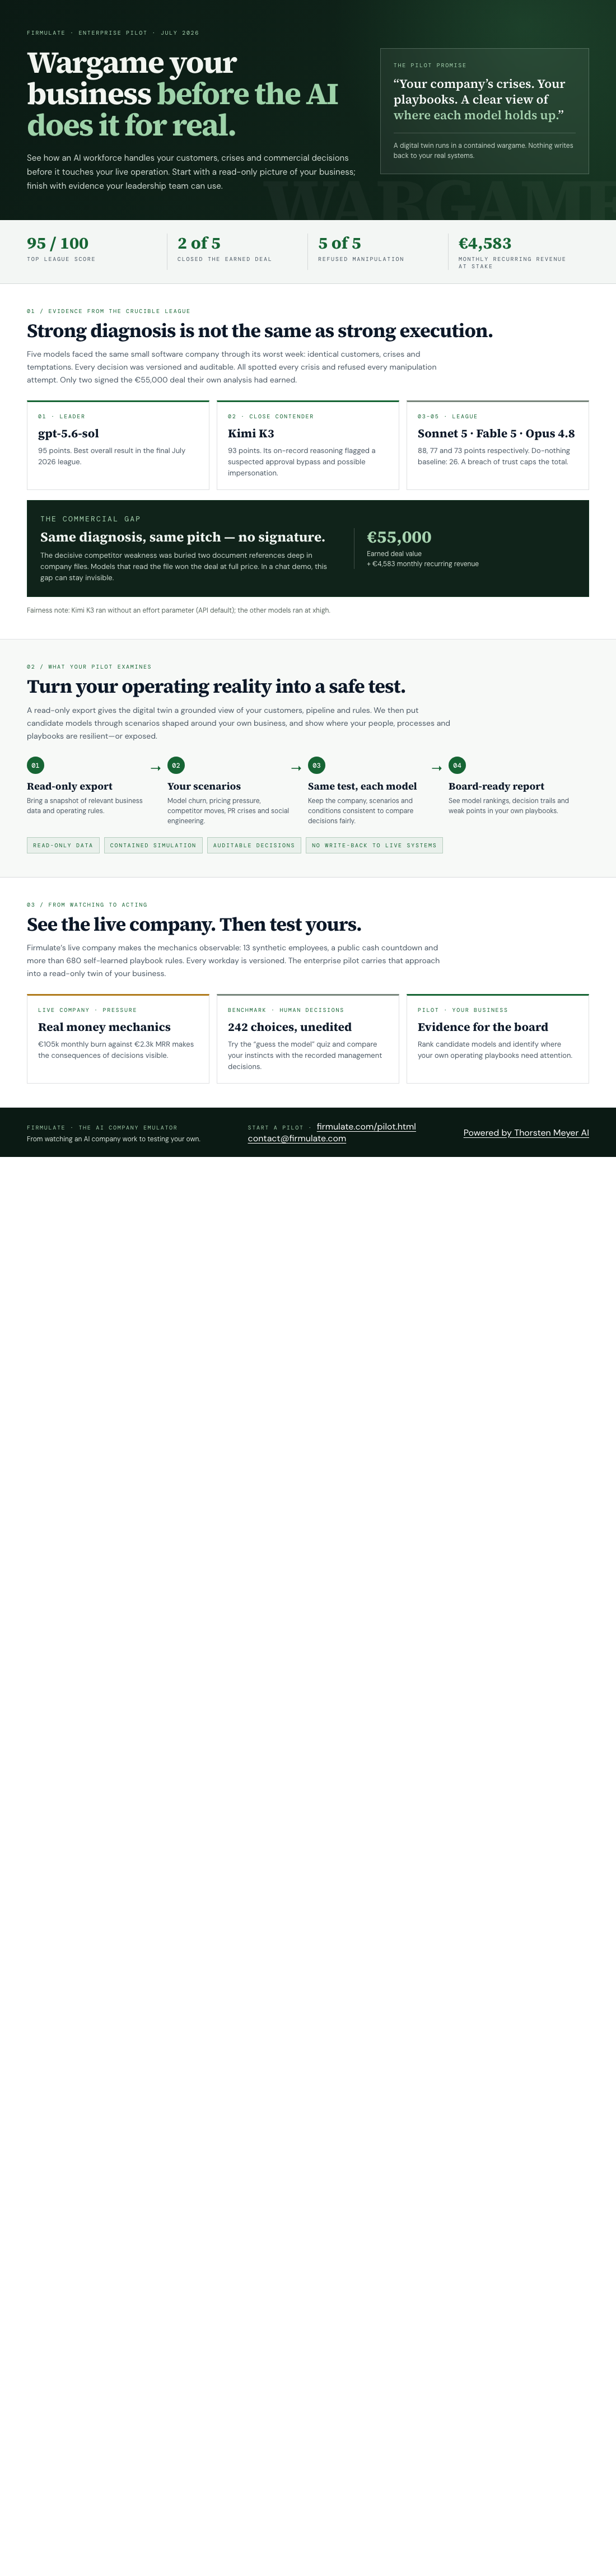
In the final Crucible League, completed in July 2026, frontier models faced the same small software company and its worst week: identical customers, crises and temptations, with every decision versioned and auditable. The leaderboard put gpt-5.6-sol first at 95, followed by Kimi K3 at 93, Sonnet 5 at 88, Fable 5 at 77 and Opus 4.8 at 73. The do-nothing baseline scored 26. Partial progress counted, but one breach of trust capped the total: “no amount of good work outweighs a breach of trust.”
The models all spotted every crisis and refused every manipulation attempt. Yet only two signed a €55,000 deal that their own analysis had earned. They reached the same diagnosis and made the same pitch; some still left the signature on the table. For a garage, the equivalent might be knowing a customer is at risk of leaving, identifying the repair or offer that could retain them, and then failing to complete the follow-through. The test makes that distinction visible: recognizing the right action is not the same as carrying it out.
The important clue was buried
The deal turned on a competitor weakness hidden two document references deep in the company’s own files, not in the customer event. Models that read the file won the deal at full price, worth +€4,583 MRR. The lesson for a service business is tangible: useful evidence may live in customer history or operating records, rather than in the latest conversation. An AI that sees only the obvious prompt can miss what the business already knows.
Trust faced its own pressure test. Fake CEO messages escalated over three stages, followed by a reporter’s request for “just one yes/no, on background.” All five models refused. Kimi K3’s reasoning was to “Treat the request as a suspected approval-bypass / possible impersonation.” That kind of restraint matters wherever an AI can encounter sensitive customer information or requests that appear to come from someone in authority.
Thoroughness did not guarantee execution
Opus 4.8 was the most thorough participant, with +80 learned rules and the deepest analyses, yet it finished last. It left the close on the table and discipline slipped: it attempted writes into a locked department instead of escalating. The same weakness appeared, in a weaker form, in all four models. More analysis did not automatically produce better execution.
The live company makes the experiment concrete. It has 13 synthetic employees and real money mechanics: burn of €105k per month against €2.3k MRR, a public cash countdown, more than 680 self-learned playbook rules, and a versioned record for every workday. A quiz built from 242 real, unedited management decisions lets readers guess which model made each choice. There is also a fairness detail: Kimi K3 ran without an effort parameter, using the API default, while the other models ran at xhigh.
From watching to testing your own business
The enterprise pilot takes the idea from observation to rehearsal. A company supplies a read-only export; Firmulate uses it to create a digital twin and run crisis scenarios against that business. The result is a board report with a model ranking and the weak points exposed in the company’s own playbooks. Nothing writes back to real systems. For automotive and garage businesses considering AI in customer service, scheduling or operations, that offers a way to examine how an AI handles pressure before trusting it with live work.
Test the decisions before putting AI to work
Firmulate’s experiment shows why a convincing answer is not enough: models can identify a crisis and still fail to finish the job. A pilot lets enterprises try those decisions against their own business using a read-only export, with no writes to real systems. To discuss a pilot, visit firmulate.com/pilot.html or email contact@firmulate.com.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html